What deepfake detection robustness testing measures
A detector that scores well on clean files can fail once those files pass through a messaging app, a contact centre or a mobile upload. Each step throws away information, and some of what it throws away are the subtle traces detectors rely on. Transformation testing measures how much detection quality is lost along each real delivery path, so you know which channels a detector can be trusted on and which need extra controls.
The research record shows why this matters. The FaceForensics++ benchmark, published in 2019, deliberately used manipulations at random compression levels and sizes because compression changes results. The Deepfake-Eval-2024 study found open-source detectors lost about half their AUC on deepfakes that had circulated online, where re-encoding and reposting are routine. NIST AI 100-4 likewise treats performance under content modification as a central question for detection and provenance techniques alike.
Which transformations should a deepfake detector be tested against?
Start from your channels, not from a generic list. Watch what actually happens to a file between the user's device and the detector, and record codec, resolution, frame rate, sample rate and file size at each hop. Then rank the transformations by how often they occur and how much damage a miss would cause on that path.
Include ordinary handling as well as attacker tricks. Many transformations are benign platform behaviour, and a test that treats them as manipulation will produce misleading results.
| Channel | Common transformations | Risk to detection |
|---|---|---|
| Mobile selfie upload | JPEG or HEIC compression, resizing, beauty filters, auto-enhancement | Lost manipulation traces; filters can trigger false positives |
| Messaging and social reposts | Repeated re-encoding, cropping, metadata stripping, screenshots | Fakes laundered until traces fade; provenance removed |
| Video calls and recordings | Variable bitrate, frame drops, frame-rate conversion, screen recording | Temporal cues broken; frame-level signals weakened |
| Contact centre audio | Narrowband telephone codecs, resampling, noise suppression | Spectral cues of synthetic speech removed |
| Claims and document portals | Photos of screens, scans, PDF conversion, rotation | Moire and rescan artefacts confuse image models |
How to build a paired transformation test matrix
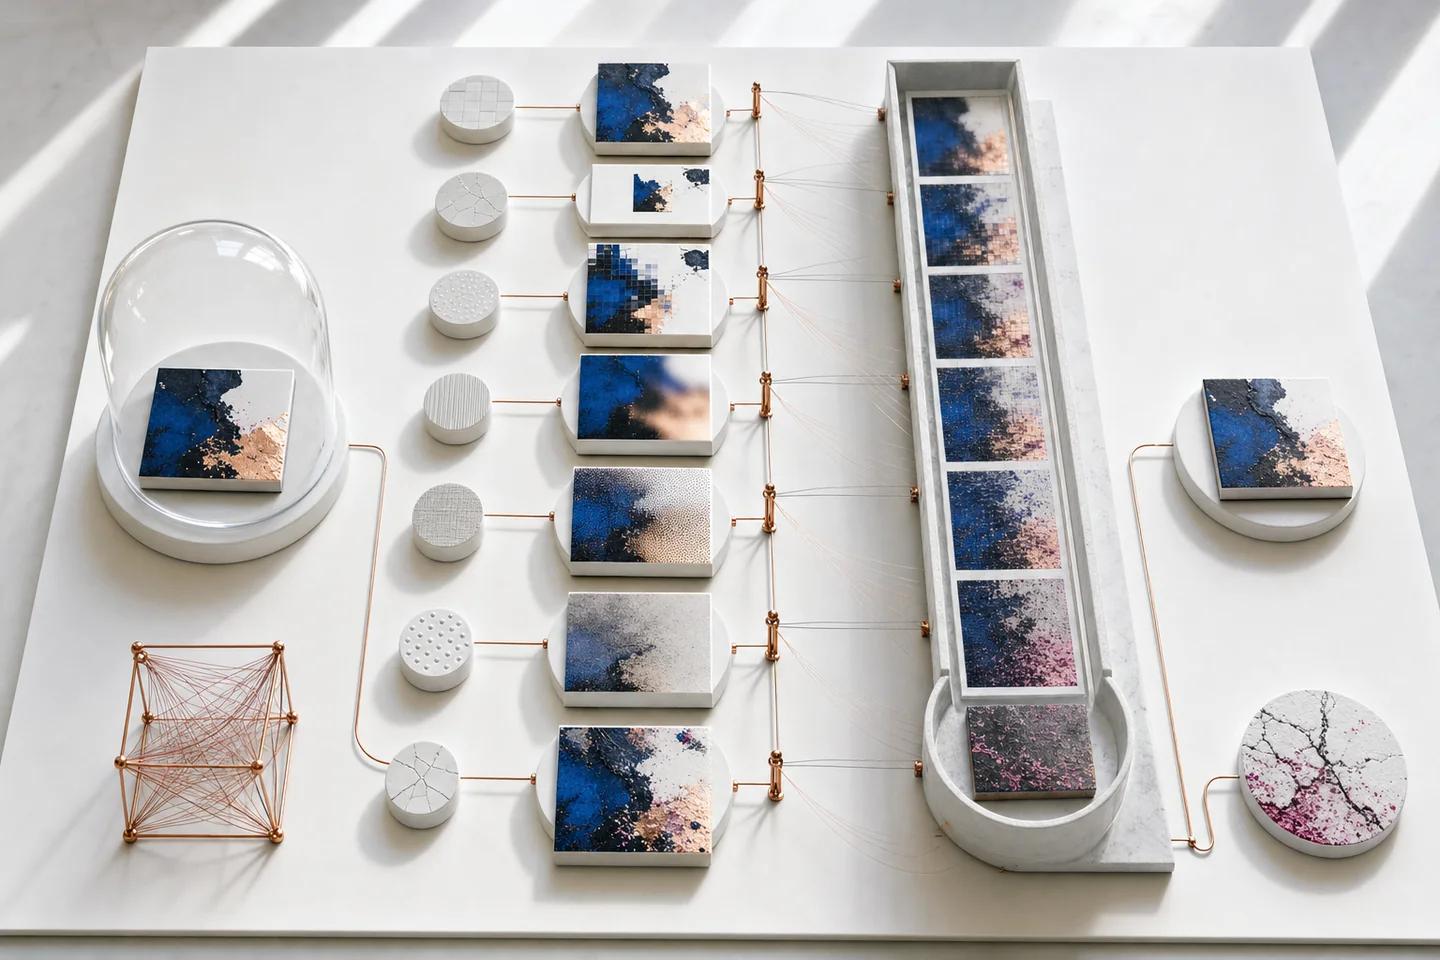
Take a balanced set of authentic and synthetic originals and keep each one as the control. Apply one transformation at a time at the parameter levels you see in production, plus the boundary levels your input rules still accept. Then apply ordered chains that copy real paths, for example a selfie compressed by the app, resized by your backend and screenshotted by a fraudster before resubmission.
Freeze the detector configuration and threshold before the run, and give every candidate system exactly the same derivative files. Record the tool and version used for each transformation so the matrix can be rebuilt. Quarantine outputs that fall outside your input contract and count them as unsupported rather than forcing a score.
For each cell, report the share of pairs whose decision flips from the original, the average score shift, MCC at your threshold, inconclusive and error rates, and latency. Flip rate is the most readable number for business owners: it says how often a transformation changes the outcome.
Why transformations raise false positives as well as misses
Most testing focuses on whether compression lets a fake slip through. The reverse failure gets less attention and costs real customers. Heavy compression, aggressive noise reduction and phone beauty modes add smooth textures and blocky artefacts that some detectors associate with generation. An older budget phone in poor light can produce a selfie that scores as more suspicious than a good face swap.
Measure flip rates separately for real and fake originals. If authentic files flip to high risk after a common transformation, the fix may be a capture change, such as asking the app to send the original rather than a re-compressed copy, instead of a looser threshold.
What happens to C2PA provenance when media is transformed
C2PA Content Credentials bind signed metadata to an asset. Some edits update the manifest correctly; many re-encoding and upload steps detach or remove it. Test whether each transformation preserves, updates, invalidates or strips the manifest, and record the validator and result codes.
Report provenance outcomes separately from detection scores. A missing manifest is the normal state for most media online and says nothing about whether a file is synthetic. A valid manifest says who signed the asset, not that the scene is real.
Signing off a channel from the results
Turn the matrix into a channel decision. For each delivery path, compare the flip rate, error rates and inconclusive rate against limits agreed before the test. A channel passes when every tested transformation in its observed range stays inside those limits. It passes with conditions when only boundary inputs fail and a fallback exists, such as asking the user to recapture or sending the case to review. It fails when common, everyday transformations push errors past the limit.
Write the result down as a supported input contract: accepted formats, minimum resolution or bitrate, and what happens to files below it. Then monitor it. If a messaging platform or your own app changes how it compresses media, the contract is out of date until the affected cells of the matrix are rerun.
- Approve: all observed transformations within limits.
- Approve with conditions: boundary inputs fail, with a defined recapture or review fallback.
- Reject: common transformations exceed the agreed error limits.
How Neural Defend handles transformed media
The VendorBench-100 corpus was built from hard cases, including compressed research frames, images with opaque provenance and AI photo edits, and Neural Defend ranked first of 36 systems on it with an MCC of 0.876 against 0.646 for the next-best vendor. One VendorBench author also co-authored our ARCAS 1B paper, so we point buyers to the public corpus to rerun it. The ARCAS paper also reports 99.92 percent pooled accuracy on WildFake, a dataset gathered from varied online sources.
In production, NeuroVerify combines six signals, including AI pixel-level manipulation and face manipulation detection, so a single weakened cue does not decide the result. Bring your channel's derivatives to the evaluation; we will score the full matrix and return per-pair results.
Evidence boundary
Limitations
- A transformation matrix covers the paths you observed; platforms change their processing without notice, so results need periodic retesting.
- Lab-applied transformations approximate but do not exactly reproduce every device and app version in the field.
- VendorBench-100 includes compressed frames but covers still images only, not video, audio or live capture paths.
Source record
Sources and references
- arXivFaceForensics++: Learning to Detect Manipulated Facial ImagesPublished January 25, 2019. Verified October 19, 2026.
- arXivDeepfake-Eval-2024: A Multi-Modal In-the-Wild Benchmark of Deepfakes Circulated in 2024Published March 4, 2025. Verified October 19, 2026.
- National Institute of Standards and TechnologyNIST AI 100-4: Reducing Risks Posed by Synthetic ContentPublished November 20, 2024. Verified October 19, 2026.
- Coalition for Content Provenance and AuthenticityC2PA Technical Specification 2.4Verified August 7, 2026.
- arXivVendorBench-100: A Unified Cross-Paradigm Benchmark for Deepfake Image Detection (v2)Published July 29, 2026. Verified October 19, 2026.
- arXivBenchmarking Neural Defend ARCAS 1B: A Foundational Multimodal Deepfake Detection ModelPublished September 21, 2026. Verified October 19, 2026.